I needed one visual style to hold across more than 50 architectural images. Prompting alone kept drifting. A small style LoRA trained through fal.ai made the palette and rendering treatment far more consistent without requiring a custom training environment.
The architectural examples below came from that workflow. They are no longer used as automatic post headers because rotating unrelated landmarks through technical articles felt arbitrary. The useful result is the trained adapter and the image set, not the old page layout.
The two-call pattern
The core workflow is still two operations:
- Upload your reference images to fal storage.
- Start the training job.
import { fal } from "@fal-ai/client";

// Upload images
const datasetUrl = await fal.storage.upload(zipBlob);

// Train
const training = await fal.subscribe("fal-ai/flux-lora-fast-training", {
  input: {
    images_data_url: datasetUrl,
    trigger_word: "aclvisual",
    is_style: true,
    steps: 1000,
  },
  logs: true,
  onQueueUpdate: update => {
    if (update.status === "IN_PROGRESS") console.log(update.logs);
  },
});

const loraUrl = training.data.diffusers_lora_file.url;
console.log("LoRA ready:", loraUrl);
That shape matches the current FLUX LoRA fast trainer. For style training, is_style: true matters: fal’s style LoRA guidance explains that it disables subject-oriented captioning and segmentation behavior.
Inference is a separate call. The trained weights now go in the loras array, and the trigger word belongs in the prompt:
const generation = await fal.subscribe("fal-ai/flux-lora", {
  input: {
    prompt:
      "aclvisual, Golden Gate Bridge, ukiyo-e woodblock print, flat color blocks",
    image_size: { width: 1200, height: 675 },
    num_inference_steps: 28,
    guidance_scale: 3.5,
    loras: [{ path: loraUrl, scale: 0.9 }],
  },
});

console.log(generation.data.images[0].url);
The FLUX.1 LoRA inference endpoint handles the base model and adapter together. No GPU provisioning or model server is part of the application code.
What the adapter produced
These three outputs use different structures and locations, but hold a similar cream background, muted blue depth, flat color treatment, and architectural framing.
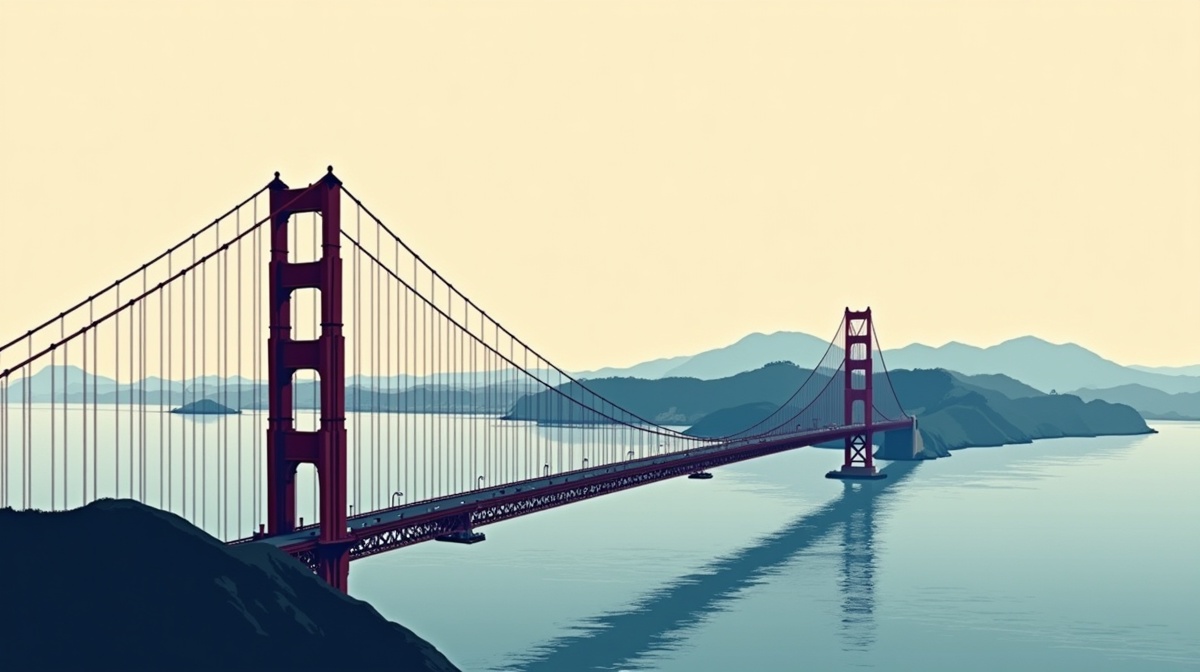 Golden Gate Bridge: long-span geometry and the restrained palette hold together.
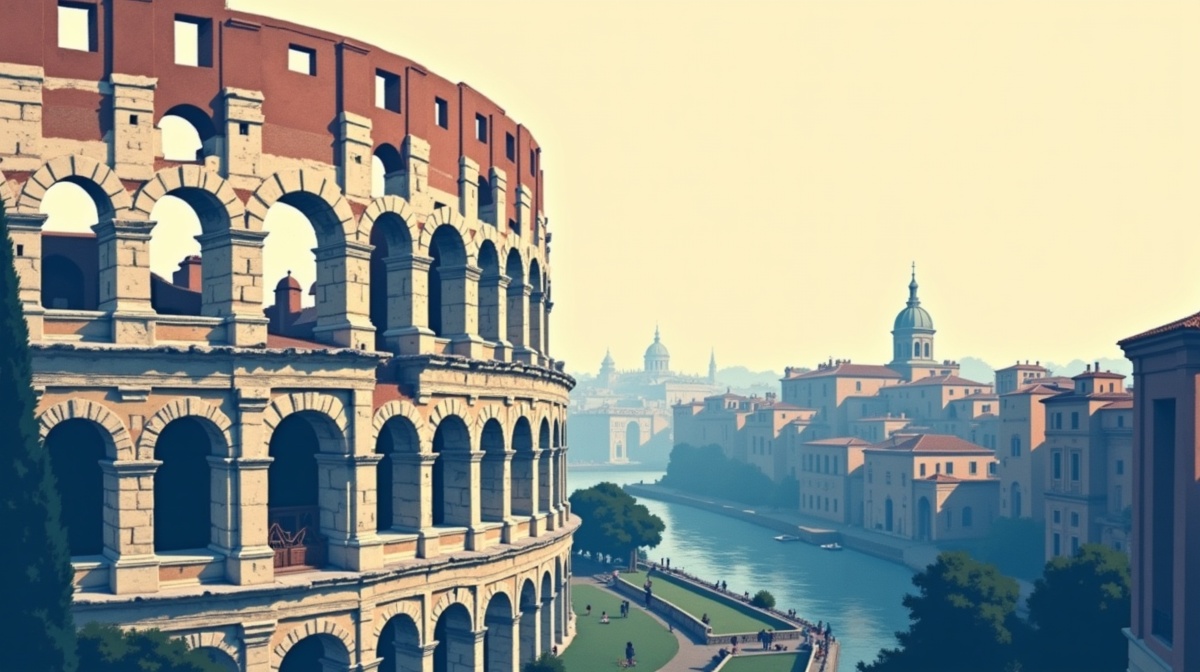 Colosseum: the same treatment carries from steel infrastructure to ancient stone.
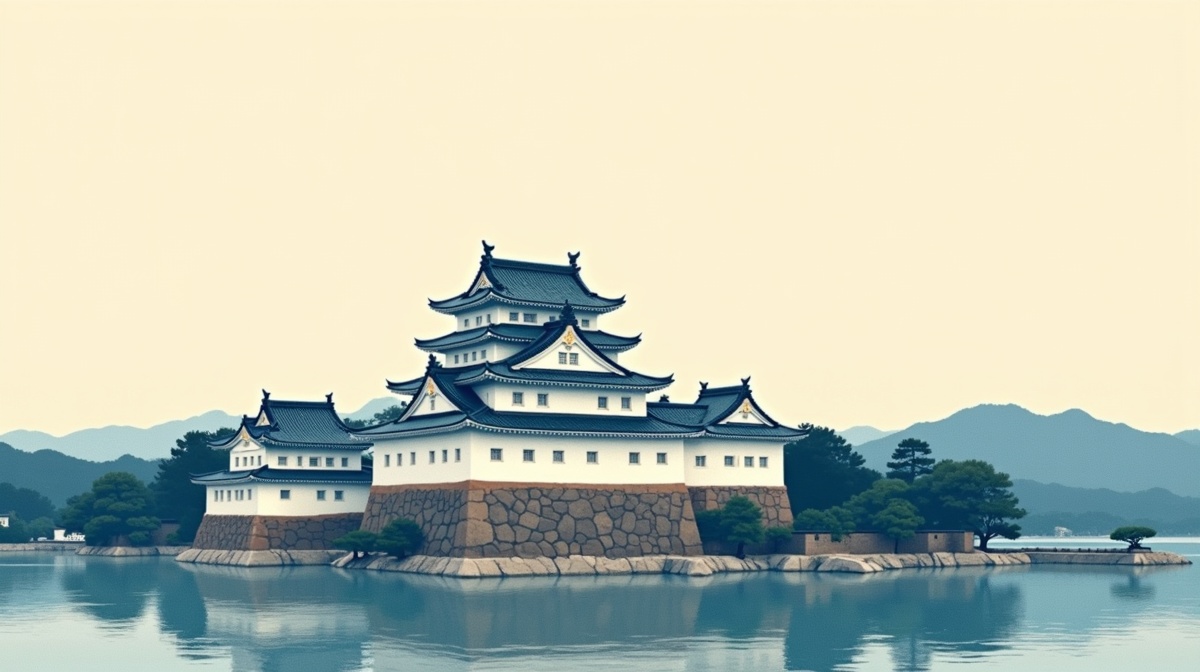 Himeji Castle: a third subject retains the same visual system without repeating the composition.
What actually surprised me
- The training set was a ZIP file, not a custom dataset pipeline.
- The hosted trainer returned a portable LoRA weights file that could be used immediately or downloaded.
- The endpoint runs through fal’s queue, so the training work is not tied to a local GPU process.
- The listed price is $2 for a 1,000-step training run and scales with the step count. Inference is priced per megapixel.
I trained this adapter on 14 approved samples, then generated the broader architectural catalog from it. The useful shift was not merely lower cost. Style stopped being a long instruction that every prompt had to renegotiate and became a reusable input to the generation call.
Where it still falls short
Style consistency is not the same as subject accuracy. The adapter can hold palette, line treatment, and composition while the base model invents structural details. That is acceptable for decorative illustration. It is not acceptable when the image needs to document a real building faithfully.
The hosted endpoint also exposes fewer training controls than a custom Diffusers pipeline. Custom schedulers, tightly controlled captions, multi-concept training, and deeper evaluation still push the workflow toward a configurable training environment.
The other limitation is model scope. This workflow is specifically for FLUX.1 [dev]. fal now has a separate FLUX.2 trainer, so moving to the newer base model is a new training and evaluation decision, not an automatic endpoint rename.
So what
Hosted LoRA training changes the fine-tuning decision. The first question is no longer whether a team can operate the training infrastructure. It is whether the desired behavior is stable enough to encode, whether the reference set represents it, and how the result will be evaluated.
The open thread is evaluation. A style adapter can look convincing across three hand-picked images and still fail on the fiftieth prompt. The missing piece is a compact benchmark for visual consistency and subject fidelity that can decide whether a newly trained adapter is ready to replace the previous one.